The British-built model passes on short answers and comes apart on long documents
Solid on brief queries; on documents running to many pages the error rate climbs.

On short questions the model meets expectations. What the testing group flagged is longer material: past about ten pages, the summary starts accurately and muddles the detail towards the end.
The benchmarks themselves are part of the story. Scores tuned on one kind of corpus give a different result on official documents written in dense legal English.
On security the rule has not moved: the weak link is never the software, it is the user in a hurry.
How the test was run
What decides how fast this spreads is not the technology but how long older handsets keep getting updates.
At the user end what changes is usually just the interface. The real change happens behind it, where nobody is looking.
What is still missing
Manufacturers tend not to comment on this sort of thing. By now the silence counts as information too.
The group says the long-document test needs repeating before anything like this summarises case files in the public sector. The result is not bad; it is not yet at the level where the human check comes out.
Leak: the new handset’s camera housing appears for the first time
The images are unconfirmed, but two separate sources show the same layout.
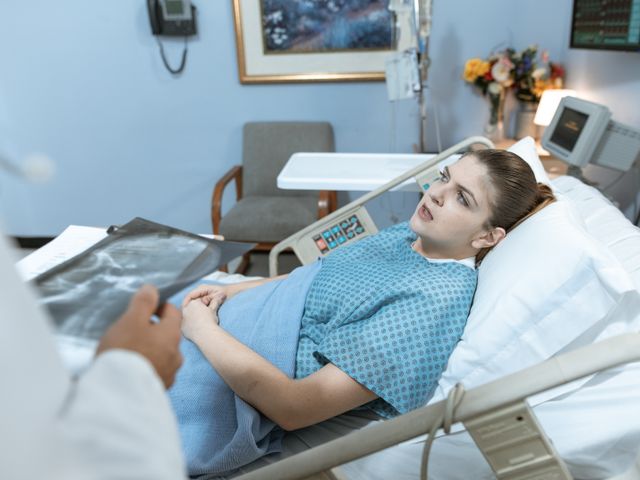
AI-assisted scan reading begins at three hospitals
The system does a first pass in radiology; the report is still signed by a doctor.
The new wave of delivery scams comes by phone, not by text
Instead of a link, the caller talks the victim into opening their own banking app.